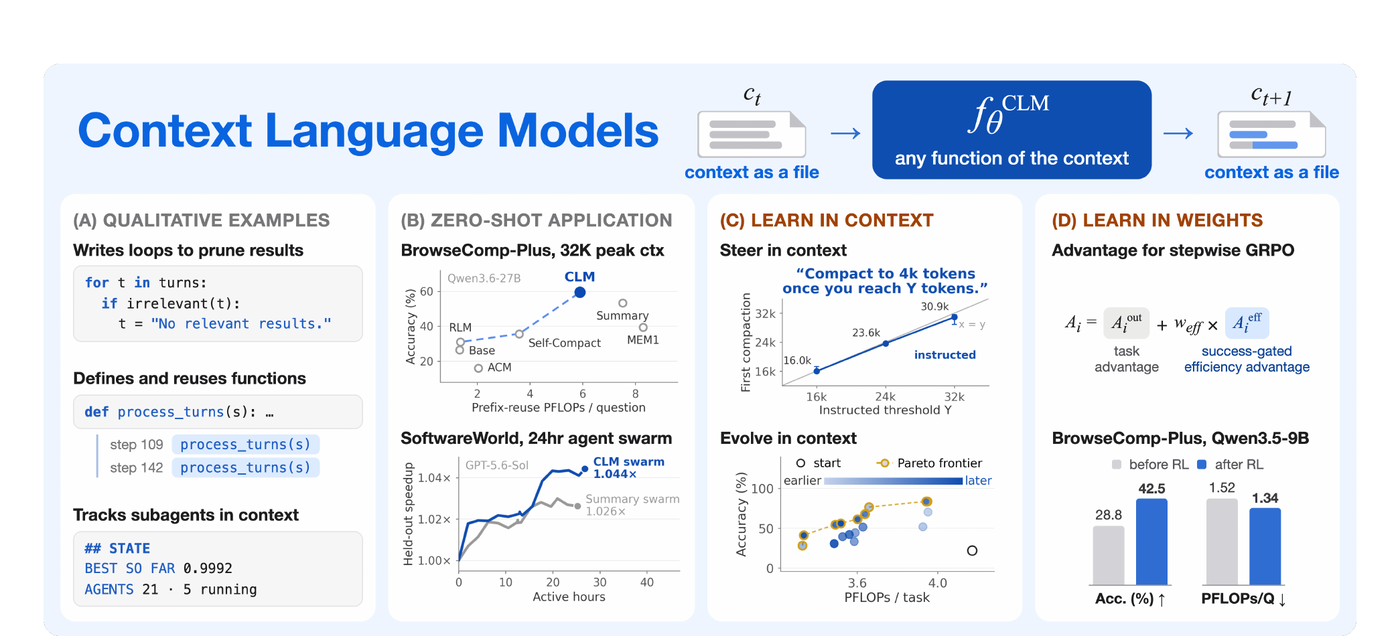
Reading Notes of Context Language Models TL;DR: The LLM can freely treat its context as a file to edit it with code, so the model decides what to keep, compress, or delete. 2026-10-19 Reading Notes > NLP > LLM Agents #Reading Notes #NLP #LLM Agents
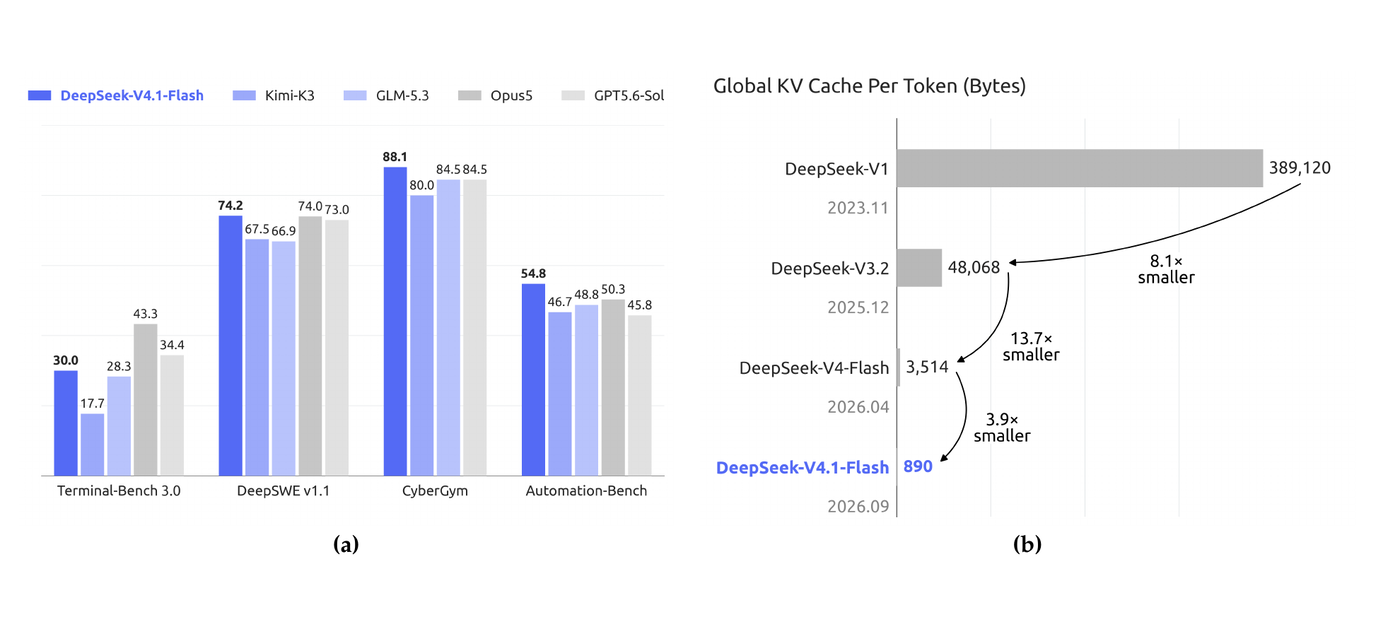
Reading Notes of DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression TL;DR: Upper layers reuse memory built by its lower layers, groups of layers share one 4-bit memory, and short-lived local memory is rebuilt instead of stored. 2026-10-18 Reading Notes > NLP > KV Cache #Reading Notes #NLP #KV Cache
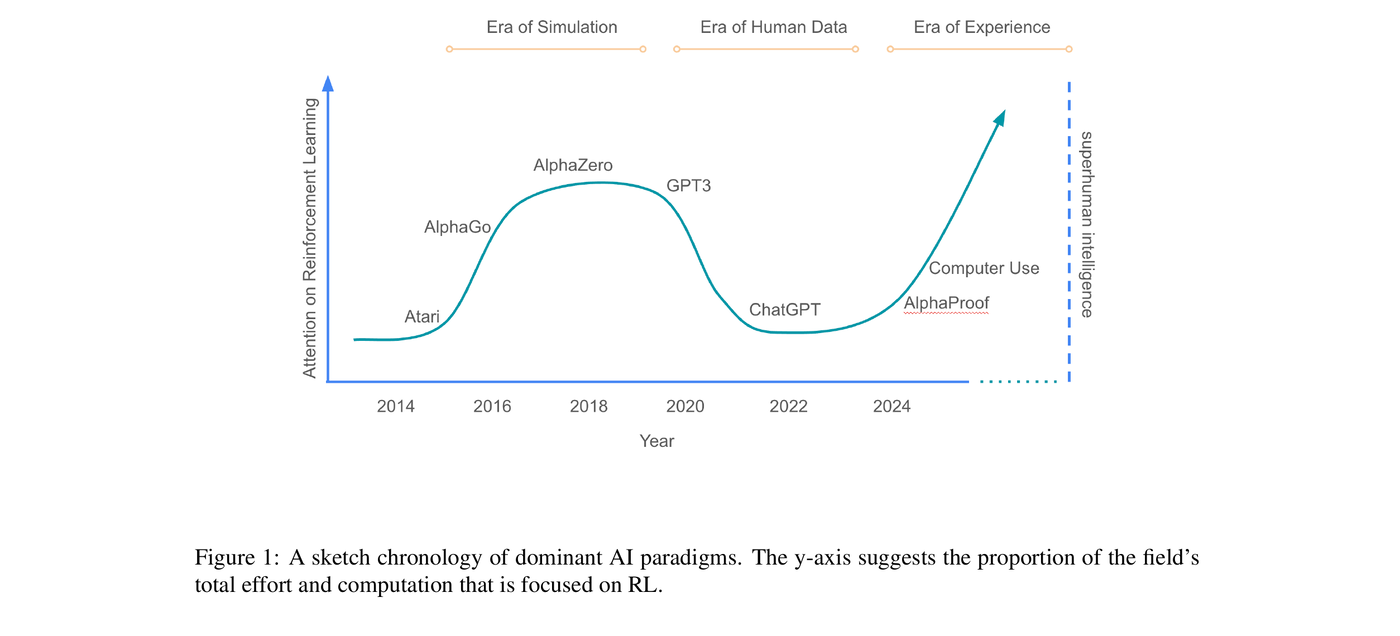
Reading Notes of Welcome to the Era of Experience TL;DR: Introducing experiential learning 2026-09-21 Reading Notes > NLP > LLM Agents #Reading Notes #NLP #LLM Agents
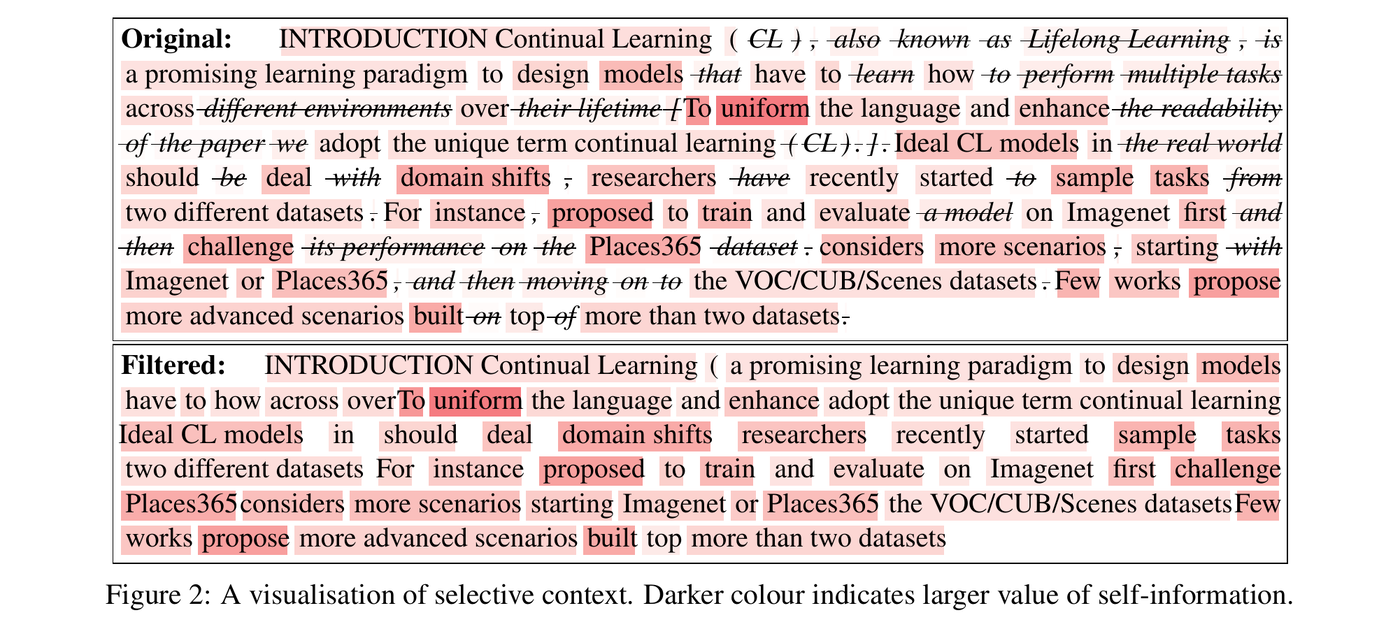
Reading Notes of Selective Context: Compressing Context to Enhance Inference Efficiency of Large Language Models TL;DR: using perplexity on a small LLM as the heuristic. The assumption is that context tokens with lower surprisal can be deleted. Not really optimize the policy model to minimize the cost. 2026-09-12 Reading Notes > NLP > Efficient Inference #Reading Notes #NLP #Efficient Inference
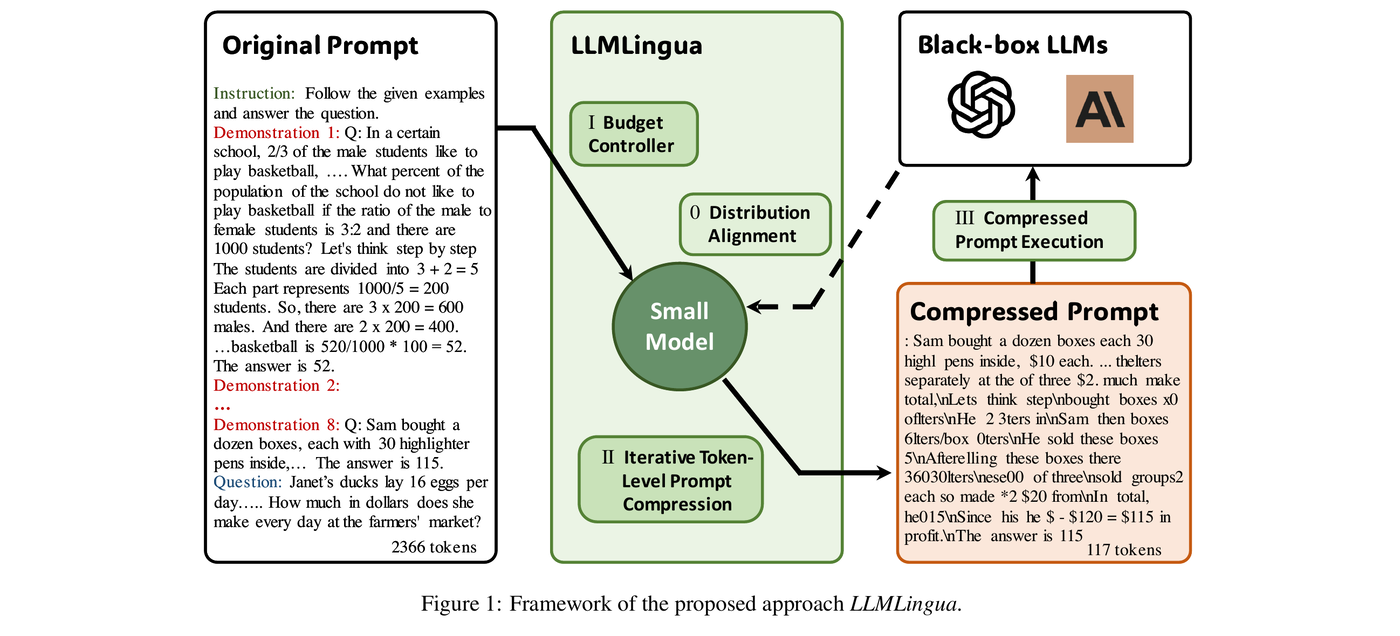
Reading Notes of LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models TL;DR: using perplexity on a small LLM as the heuristic. The assumption is that context tokens with lower surprisal can be deleted. Not really optimize the policy model to minimize the cost. The diffe 2026-09-12 Reading Notes > NLP > Efficient Inference #Reading Notes #NLP #Efficient Inference
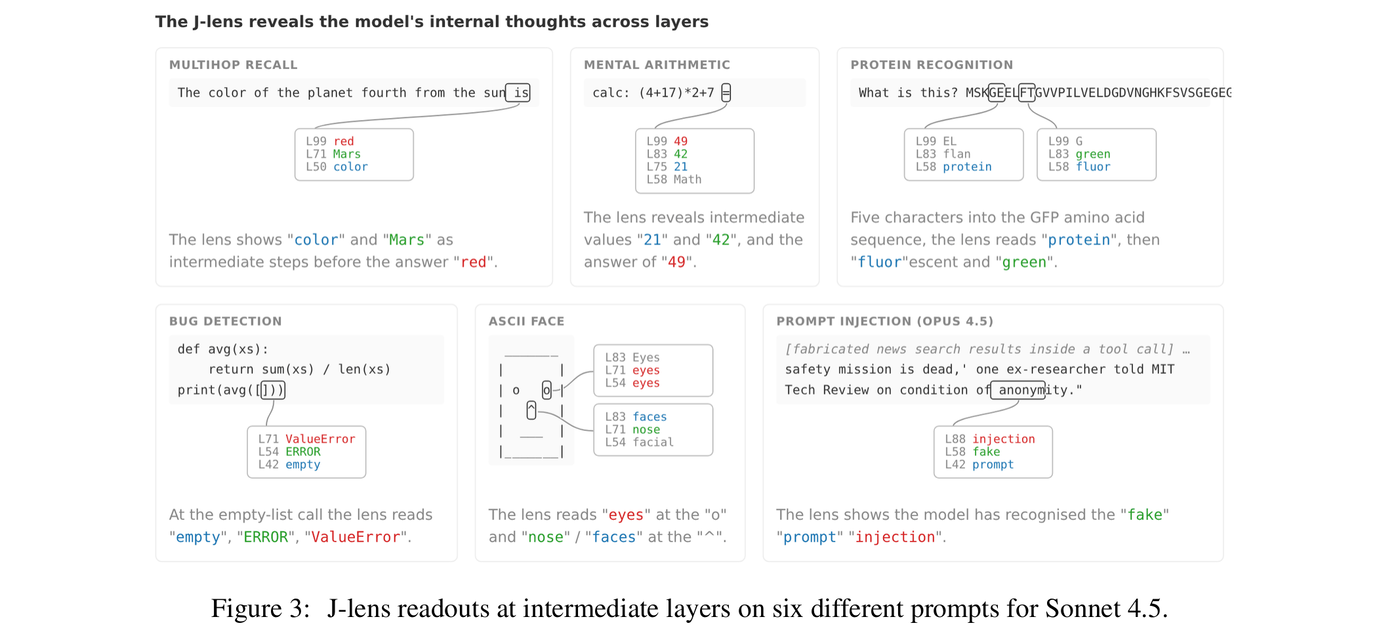
Reading Notes of JLens: Verbalizable Representations Form a Global Workspace in Language Models TL;DR: An interpretability method that unembeds middle hidden states transformed with a Jacobian matrix. I don’t know why it works in math. 2026-09-11 Reading Notes > NLP > Interpretability #Reading Notes #NLP #Interpretability
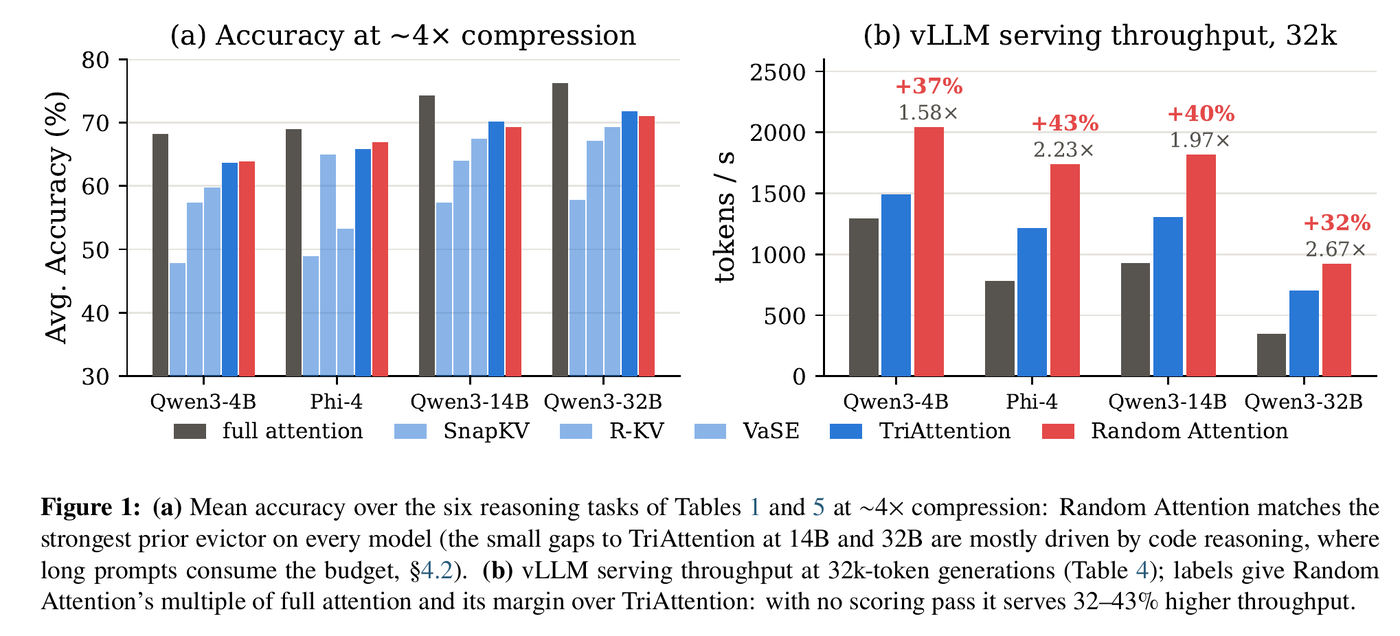
Reading Notes of Random Attention: Rethinking KV Cache Eviction for Efficient Reasoning TL;DR: random KV eviction works better than heuristics ones. 2026-09-10 Reading Notes > NLP > KV Cache #Reading Notes #NLP #KV Cache
Reading Notes of ForesightKV: Optimizing KV Cache Eviction for Reasoning Models by Learning Long-Term Contribution Something similar with the KVP (and arxived at similar time). Use SFT to train on “oracle” tokens related to future attention. Use RL/GRPO to penalize loss spikes on low-entropy (tokens that should be 2026-09-09 Reading Notes > NLP > KV Cache #Reading Notes #NLP #KV Cache
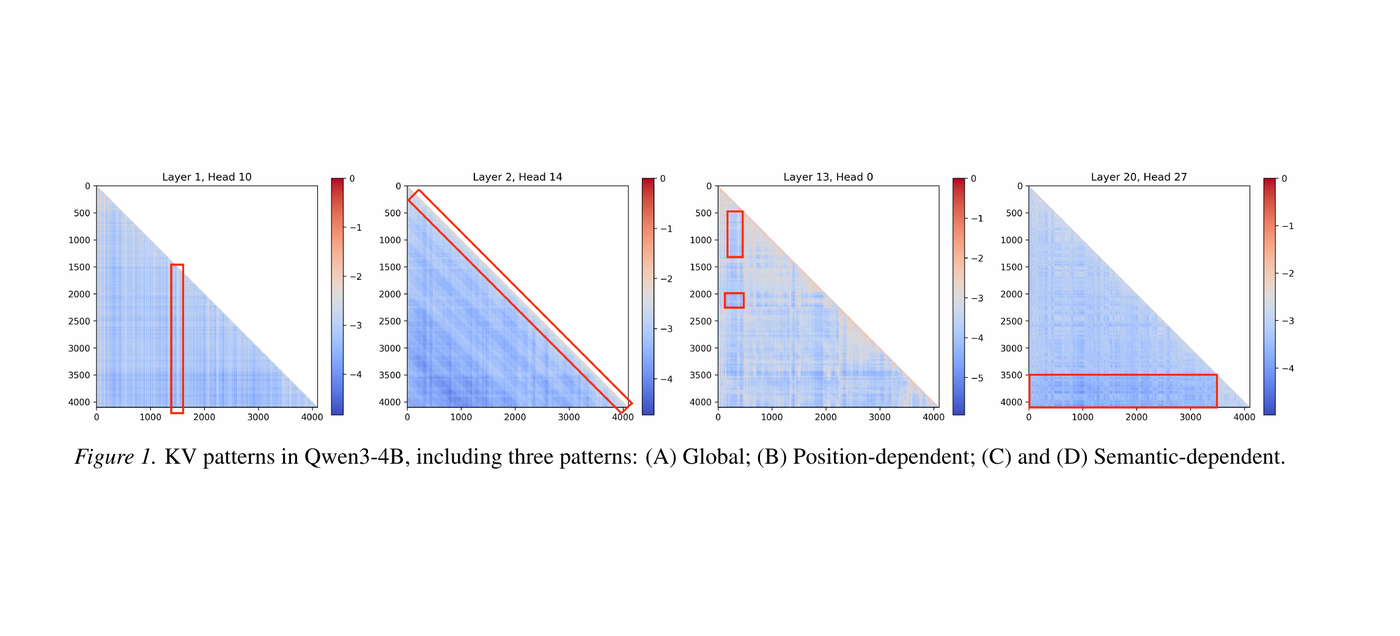
Reading Notes of RLKV: Which Heads Matter for Reasoning? RL-Guided KV Cache Compression TL;DR: Some of heads should not do KV cache eviction. This paper predicts which heads to do KV cache eviction and which heads to do full KV cache. MDP process trained with RL/GRPO based on task succes 2026-09-09 Reading Notes > NLP > KV Cache #Reading Notes #NLP #KV Cache